Drummer-540M model card
Luke Steuber (lukesteuber.com, github.com/lukeslp) · weights Apache-2.0 · this card CC BY 4.0
Drummer-540M is a small language model I trained from scratch. It is a research project, not a product. The public demo serves three models from this run: this checkpoint for completion, and fine-tunes of the 10.85B and 8.13B checkpoints for tool proposals and chat. Each is promoted only by a preregistered rule or by a decision I record.
Architecture
- Decoder-only transformer, Llama-style: 24 layers, hidden 1344, feed-forward 3584, 21 attention heads (21 key/value heads), head size 64, RMSNorm, SiLU, rotary positions (theta 10000.0), tied embeddings.
- 542,310,720 parameters; vocabulary 16,384 (byte-level BPE fitted on 10,000 Cosmopedia documents); context 2,048 tokens.
- Weights served in bfloat16; package
drummer2-540m-cont2-100pct-step-38147-pkg, weights SHA-2564c594987989bedb7….
Training
The base run first, then the continuation that produced the checkpoint above. Both belong on this page: the data mix and losses below are the base run's, and the served weights are the continuation's.
Base run
- 10,846,208,000 tokens in 82,750 updates of 131,072 tokens (sequence 2048), seed 20260913.
- Warmup-stable-decay schedule: peak learning rate 0.0005, 2000 warmup updates, constant to 80%, linear decay to 10% of peak.
- Data mix: fineweb-edu 50% (1.00 epochs); cosmopedia-v2 15% (1.00 epochs); wikipedia 15% (1.15 epochs); gutenberg 10% (0.99 epochs); dialogue 10% (1.62 epochs).
- Final held-out loss (per source): cosmopedia-v2 1.5534, dialogue 1.2776, fineweb-edu 2.4311, gutenberg 2.6398, wikipedia 1.9651; weighted 2.1351.
- Hardware: NVIDIA H200, data-parallel over 2 GPUs on Hugging Face Jobs in capped segments.
- Provenance: about 8% of these tokens were smol-smoltalk, text written by Llama-3.1-405B, and that model's licence carries a naming clause. The continuation below uses no Llama-derived text.
Continuation (the served release)
- Export
model-0038147: the base run carried on to 15.85B tokens in total, on new FineWeb-Edu, DCLM-Edu and FineMath shards with replay of the base sources. - Held-out loss: -3.46% on the old distribution and -3.43% on the new one, with replay -2.08%.
- BLiMP 0.7435 to 0.8133; lm-eval suite mean 0.4698 to 0.4821, worst single task -0.0016.
- Door 3, the preregistered publication gate: passed every clause, which is what made this Foundation 0.12.0 by rule rather than by my decision.
Releases on the public demo
- completion: 0.12.0 (2026-09-18), release
16b6cfda…, "Drummer-540M continued to 15.85B tokens (update 38,147); door 3 passed every clause" - chat: 0.18.0 (2026-09-15), release
60ddd988…, "Drummer Chat: 540M at 75% of training, Chat 0.17.0 recipe; owner decision over rule v2" - tools: 0.10.0 (2026-09-15), release
c8a5809b…, "Drummer Tools: 540M at 10.85B (Foundation 0.11.0), tool contract v2 (adds text.tail); rule v4 vs 0.9.0"
Benchmarks
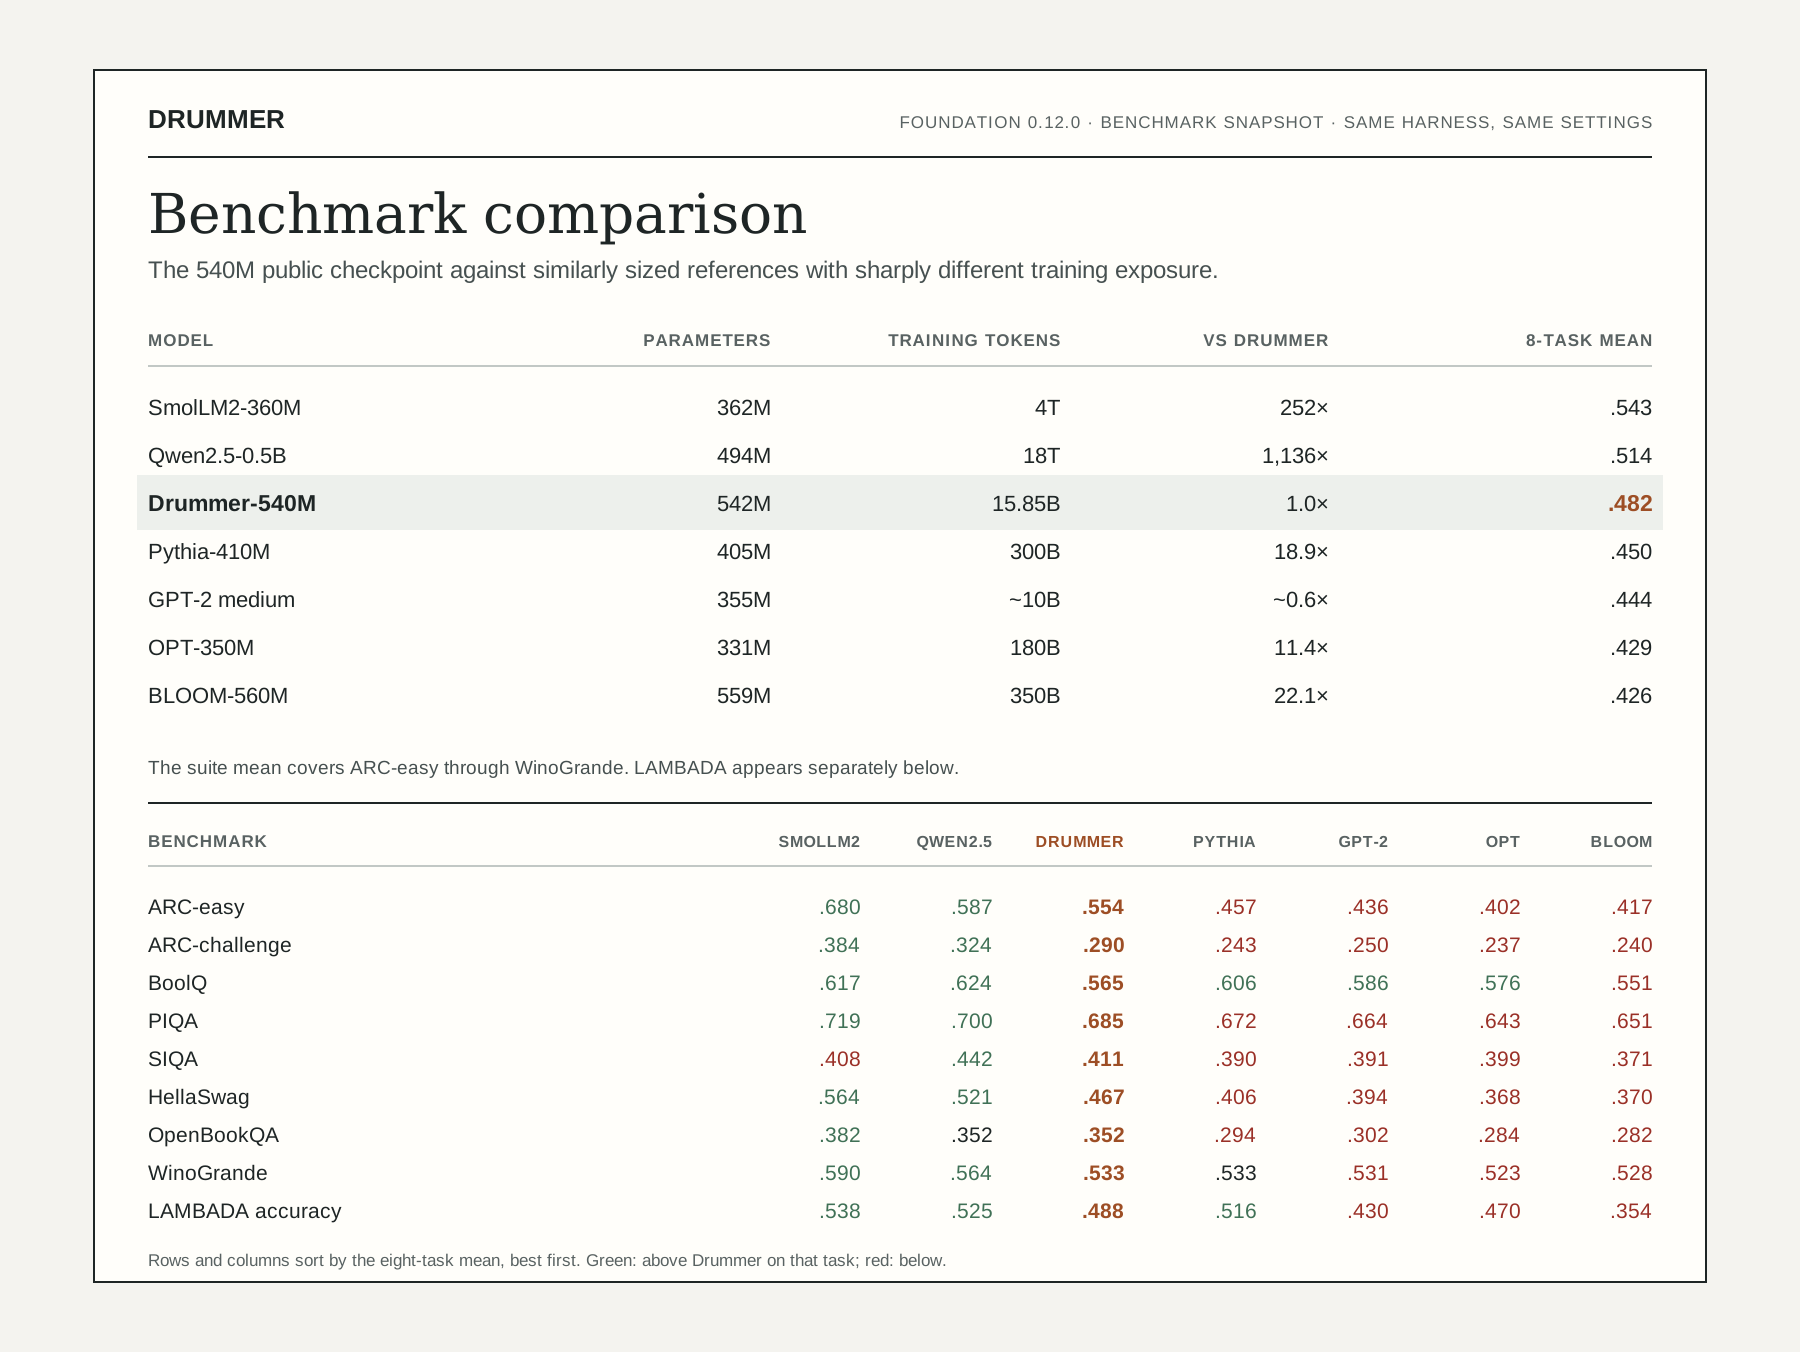
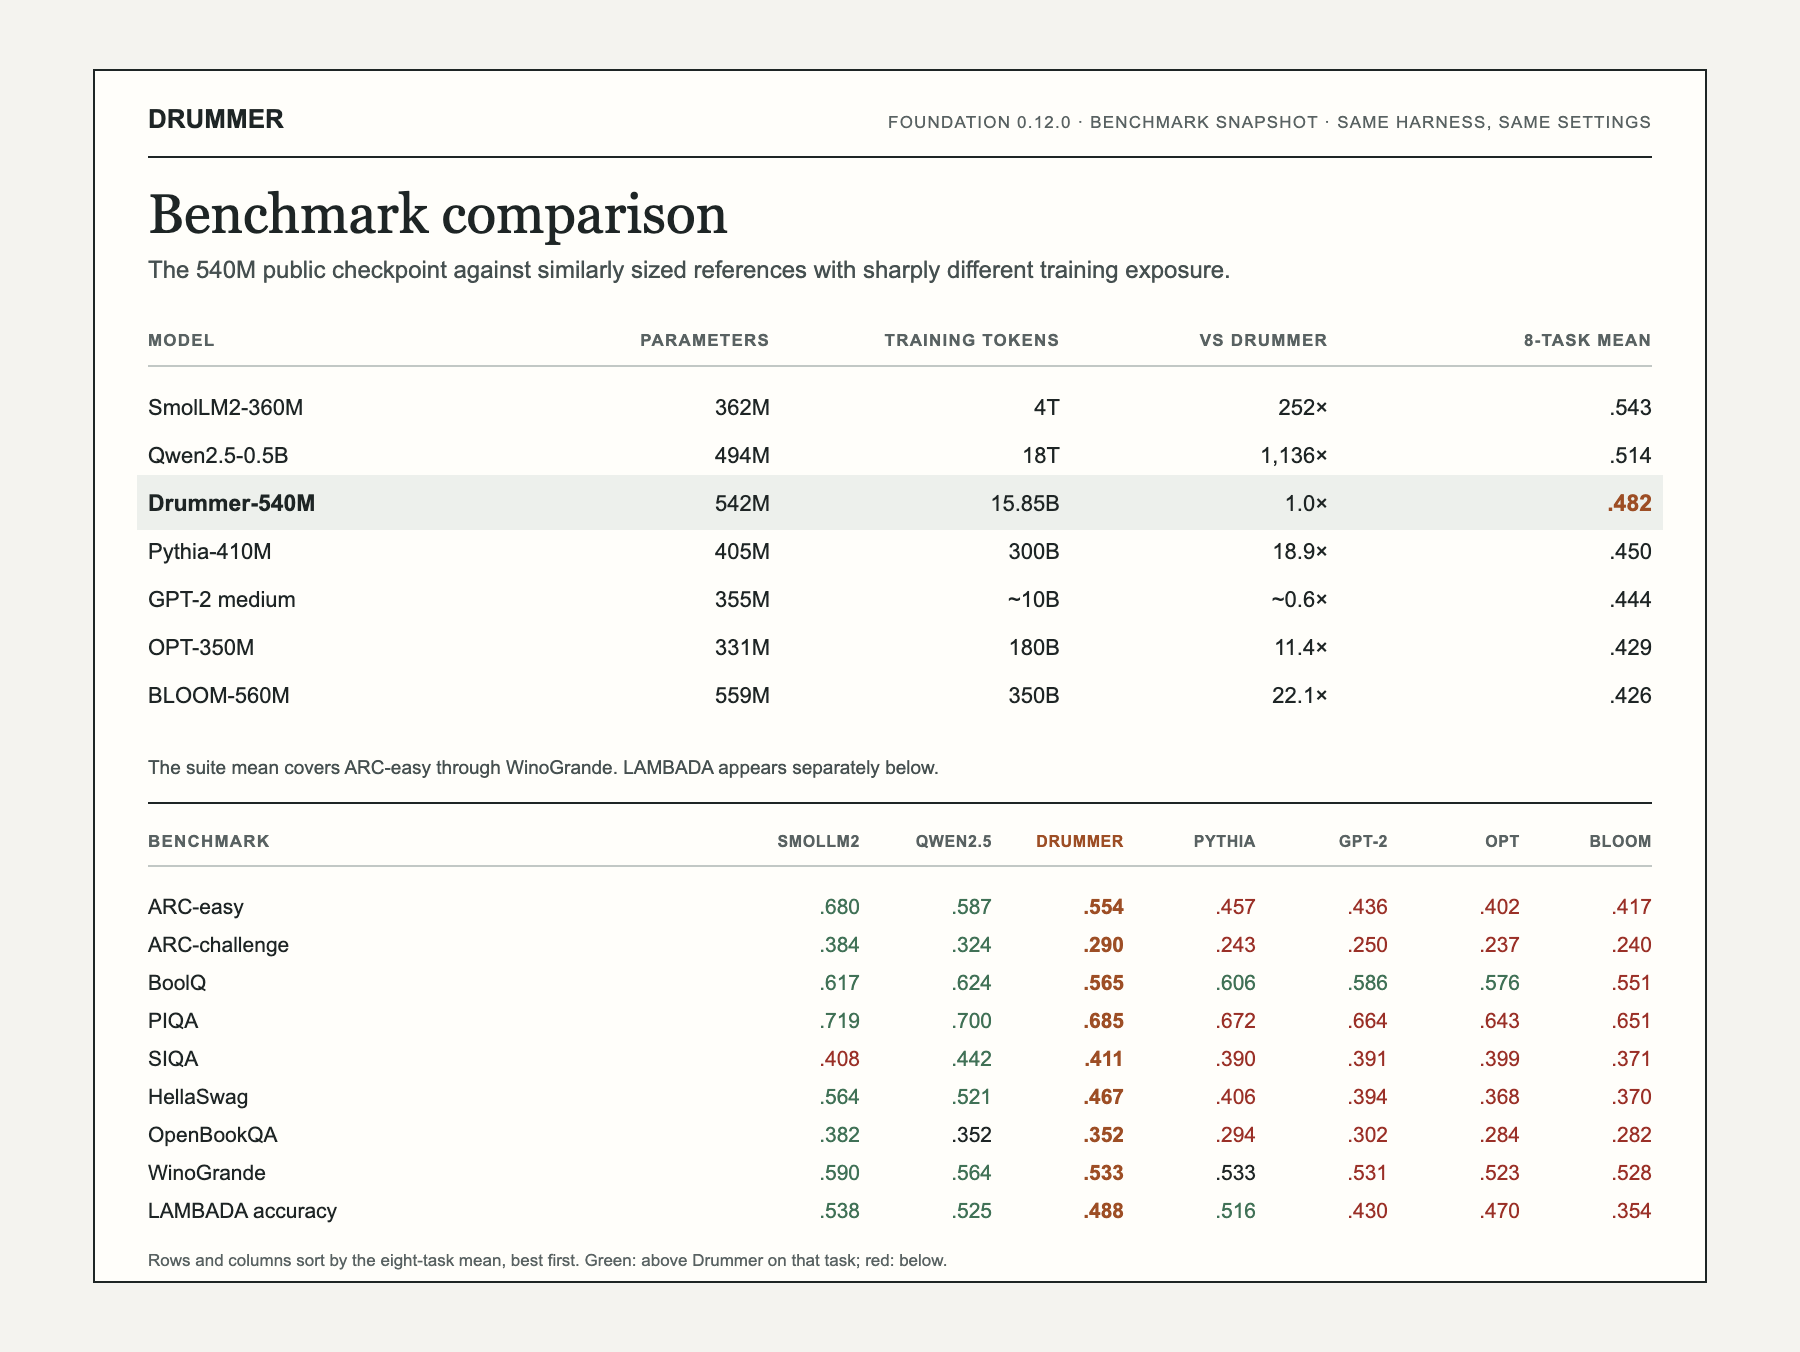
Settings: lm-evaluation-harness 0.4.13, zero-shot, float32, seed 20260915, context 2,048; Drummer runs add a BOS token; the 540M suite rows ran on the Apple GPU, peers and the extra tasks on an L4. The suite mean averages the eight MobileLLM tasks, ARC-easy through WinoGrande; the extra tasks follow. I ran every number here myself with the same harness and settings — the peers and the 0.11.0 rows on the night of 2026-09-15/16, the 0.12.0 rows when that continuation passed its door on 2026-09-18; nothing is copied from a paper.
| Model | Params | Train tokens | Suite mean | ARC-e | ARC-c | BoolQ | PIQA | SIQA | HellaSwag | OBQA | WinoG | LAMBADA | SciQ | COPA | WSC273 | LogiQA | RACE | CSQA | TruthfulQA |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| SmolLM2-360M | 362M | 4T | 0.543 | 0.680 | 0.384 | 0.617 | 0.719 | 0.408 | 0.564 | 0.382 | 0.590 | 0.538 | 0.862 | 0.780 | 0.696 | 0.289 | 0.327 | 0.198 | 0.334 |
| Qwen2.5-0.5B | 494M | 18T | 0.514 | 0.587 | 0.324 | 0.624 | 0.700 | 0.442 | 0.521 | 0.352 | 0.564 | 0.525 | 0.904 | 0.740 | 0.656 | 0.295 | 0.346 | 0.546 | 0.397 |
| Drummer-540M (Foundation 0.12.0) | 542M | 15.85B | 0.482 | 0.554 | 0.290 | 0.565 | 0.685 | 0.411 | 0.467 | 0.352 | 0.533 | 0.488 | – | – | – | – | – | – | – |
| Drummer-540M anneal v1 (not released) | 542M | 11.6B | 0.472 | 0.550 | 0.279 | 0.542 | 0.681 | 0.418 | 0.451 | 0.336 | 0.520 | 0.462 | – | – | – | – | – | – | – |
| Drummer-540M (Foundation 0.11.0) | 542M | 10.85B | 0.470 | 0.528 | 0.281 | 0.540 | 0.687 | 0.412 | 0.440 | 0.348 | 0.522 | 0.464 | 0.737 | 0.680 | 0.648 | 0.283 | 0.311 | 0.193 | 0.376 |
| Drummer Chat 0.18.0 | 542M | 8.13B + fine-tune | 0.457 | 0.519 | 0.282 | 0.529 | 0.663 | 0.405 | 0.409 | 0.328 | 0.524 | 0.474 | 0.807 | 0.730 | 0.604 | 0.267 | 0.309 | 0.188 | 0.384 |
| Pythia-410M | 405M | 300B | 0.450 | 0.457 | 0.243 | 0.606 | 0.672 | 0.390 | 0.406 | 0.294 | 0.533 | 0.516 | 0.725 | 0.680 | 0.659 | 0.296 | 0.304 | 0.196 | 0.412 |
| GPT-2 medium | 355M | ~10B | 0.444 | 0.436 | 0.250 | 0.586 | 0.664 | 0.391 | 0.394 | 0.302 | 0.531 | 0.430 | 0.672 | 0.690 | 0.612 | 0.278 | 0.308 | 0.195 | 0.407 |
| OPT-350M | 331M | 180B | 0.429 | 0.402 | 0.237 | 0.576 | 0.643 | 0.399 | 0.368 | 0.284 | 0.523 | 0.470 | 0.685 | 0.690 | 0.641 | 0.290 | 0.305 | 0.209 | 0.408 |
| BLOOM-560M | 559M | 350B | 0.426 | 0.417 | 0.240 | 0.551 | 0.651 | 0.371 | 0.370 | 0.282 | 0.528 | 0.354 | 0.717 | 0.610 | 0.623 | 0.272 | 0.312 | 0.195 | 0.424 |
| Drummer-126M (Foundation 0.6.0) | 126M | 2.5B | 0.422 | 0.433 | 0.246 | 0.580 | 0.613 | 0.378 | 0.313 | 0.290 | 0.521 | 0.295 | – | – | – | – | – | – | – |
MMLU (57 subjects, zero-shot): 0.257 for Foundation 0.11.0 (10.85B tokens), chance level, as expected for this size and token count. The served Foundation 0.12.0 checkpoint has no MMLU run on record.
BLiMP (67 paradigms × 1,000 minimal pairs, exact-match preference): Foundation 0.12.0 0.8133; Foundation 0.11.0 0.7435; anneal v1 (not released) 0.7434.
IFEval (verifiable-instruction prompts, generative): 30 of 541 prompts satisfied every instruction in them (prompt_level_strict_acc; strict and loose agree), on chat-0.18.0-ifeval, the Chat fine-tune of the 8.13B checkpoint. Small instruct models of this size score in the tens of percent here; this is the measure of how far the fine-tune is from following an instruction it has not been trained on, and it is the same limit the sealed tools test finds on the Tools fine-tune of the 10.85B checkpoint (writeup). IFEval was not run on the 15.85B model.
How to read it: GPT-2 medium saw about as many tokens as Foundation 0.11.0, so it is the fair comparison for the training recipe. SmolLM2, Qwen2.5 and the models trained on 100B tokens or more saw 11.4 to 1,136 times more text at the same size, and that is the gap to expect on HellaSwag and LAMBADA.
Intended use and limits
- Research on small-model training and on how context reaches a model. The demo exists so the model can be tried, not relied on.
- It completes and converses in English at the level 542M parameters and this much training text allow: it invents facts and contradicts itself across turns. The tool mode is Tools 0.10.0, fine-tuned from the 10.85B checkpoint; it calls only the tools it was trained on: on the sealed transfer test it made no schema-valid call to a tool that was declared in the prompt but never trained on (0 of 24 slots). It named that tool 4 times, each time missing a required argument, where two same-size models fine-tuned on the same corpus made a valid call in 10 and 11 (writeup). The same lesson retaught on this 15.85B checkpoint, at a gentler learning rate, also made 0 of 24.
- No safety tuning. Nothing typed into the demo is stored or trained on.
Meaning in context
I read the project through systemic functional linguistics. The pretrained model is the language's potential; each fine-tune moves it toward a register; the context of a conversation selects what gets said. The first study taught the 126M model explicit SFL labels and found no effect. The current one gives the model a one-line context of situation instead.
Licences and attribution
- Weights and code: Apache-2.0. This card and the project's own documentation and synthetic data: CC BY 4.0 (LICENSE-DATA.md, NOTICE).
- Training sources keep their own terms: FineWeb-Edu (ODC-By 1.0, Common Crawl terms), SmolLM-Corpus Cosmopedia v2 (ODC-By 1.0; Mixtral-8x7B output), Wikipedia (CC BY-SA 4.0), Project Gutenberg via Common Pile (public domain), SODA (CC BY 4.0; GPT-3.5 output), smol-smoltalk (Apache-2.0 data; Llama 3.1 licence naming clause on the generating model, see above).
- Continuation sources (the served checkpoint): DCLM-Edu (CC BY 4.0), FineMath (ODC-By 1.0), and a small human-transcript share from OANC Switchboard (unrestricted), QuAC (MIT) and Taskmaster (CC BY 4.0). Evaluation used lm-evaluation-harness (MIT), BLiMP (CC BY 4.0), IFEval (Apache-2.0) and MMLU (MIT); scores are reported and no benchmark data is redistributed.
Citation
Steuber, L. (2026). Drummer-540M: a small language model trained from scratch, with matched studies of context. https://drummer-demo.dr.eamer.dev
Back to the demo · Read the writeup: what the tools result does and does not show